Seinari: live demos
PrismML's Ternary Bonsai models (every weight is −1, 0 or +1) running on Seinari's own inference engines, from an RTX 5090 down to phones and browser tabs. Every link opens at its fastest single-stream setting. Every number below was measured by us on the stated device.
Live
Seinari website builder: a website from one sentenceOpen → Type "Build a website that …": PrismML's Ternary Bonsai 2 27B on Seinari's engine, on one RTX 5090, writes a self-contained page and it renders live. 370–660 tok/s decode (sampled, T=0.7), 4–11 s per page · RTX 5090. Seinari Chat: 27B on one RTX 5090Open → Multi-user chat with PrismML's Ternary Bonsai 2 27B (5.95 GB of weights) on Seinari's engine. Opens in Fast mode, the fastest single-stream setting. 1,268 tok/s single stream on the full GSM8K set (1,146/1,319 correct), speculative decoding · RTX 5090. Strict mode: 938 tok/s (1,141/1,319). Seinari in the browser: a 2B model inside a browser tabOpen → WebGPU chat with PrismML's Ternary Bonsai 2 2B on Seinari's browser engine. No server: the model downloads once (429 MB), is cached, and runs on your GPU. It picks the fastest engine for the device automatically (standard on desktops, phase-split on phones). ~100 tok/s decode on a laptop integrated GPU (Radeon 780M, Chrome) · 52 tok/s on a Galaxy S23 · 35 tok/s on a Pixel 7. Seinari Image: text-to-image in the browserOpen → Ternary Bonsai Image 4B (FLUX.2 Klein class) generating 512×512 images on the local GPU with WebGPU. 6.7 s per image on a Radeon 780M laptop iGPU vs 20.2 s for the public community WebGPU demo, at higher fidelity (58 dB vs 34 dB PSNR to the fp32 reference); first visit downloads ~3 GB once · iPhone 17 Pro 46 s, Galaxy S23 131 s, where the community demo fails to load. Fast Inference Man (short film)Open → A short animated explainer of how the 5090 engine was made fast, step by step.On-device engines
iPhone: watch it chat (video)Watch → A 30-second real-time recording of the 2B model answering three questions in a chat app, entirely on an iPhone 18 Pro Max. 197–235 tok/s in the chat · first word in 103–137 ms · raw 268 tok/s benchmark recording on the same page.
iPhone: Seinari's Metal engine
A complete Metal inference engine for PrismML's Ternary Bonsai 2 2B in an iOS app, token-identical to greedy decoding.
268 tok/s single stream on an iPhone 18 Pro Max (A20 Pro) · 165 tok/s plain greedy · 61–84 ms to first token.
Android: install the appDownload →
One Seinari app with CPU, Vulkan, OpenCL and Hexagon engines; it uses the fastest one that reproduces the reference exactly on your phone. Install it and chat with the 2B model on the phone.
131.7 tok/s single stream on a Galaxy S26 Ultra · 39 phone set-ups measured on real devices, 37 token-identical.
Server engines
RTX 5090 engine
Seinari's native CUDA engine for PrismML's Ternary Bonsai 2 27B: packed ternary weights fed straight into Blackwell FP4 tensor cores, step by step from PrismML's llama.cpp.
6,446 tok/s with 64 users at once on one RTX 5090 · 6.9× PrismML’s own engine side by side.
AMD Strix Halo engine
Seinari's from-scratch HIP engine for PrismML's Ternary Bonsai 2 27B on a Ryzen AI MAX+ 395 mini-PC (Radeon 8060S).
91 tok/s single stream with speculation, token-identical to greedy · plain decode 34.5 tok/s vs 21.0 for llama.cpp HIP (1.64×).
Quality at a fraction of the memory
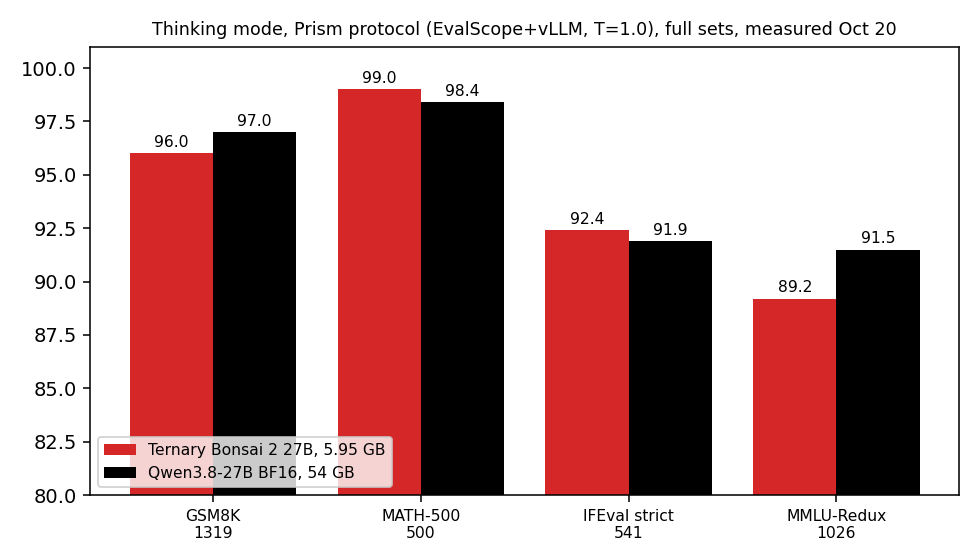
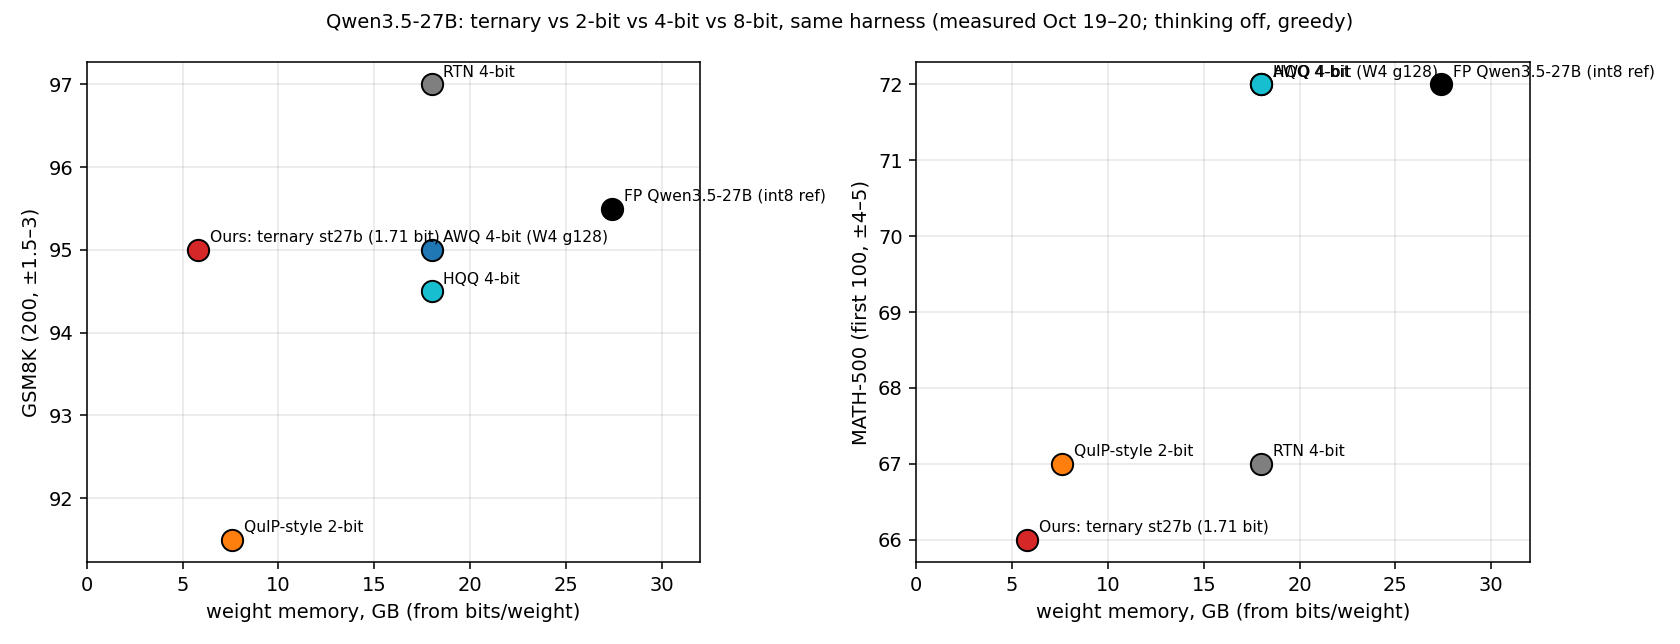
| Benchmark | Ternary Bonsai 2 27B · 5.95 GB | Qwen3.8-27B BF16 · 54 GB |
|---|---|---|
| GSM8K (1,319) | 96.0 | 97.0 |
| MATH-500 (500) | 99.0 | 98.4 |
| IFEval prompt-strict (541) | 92.4 | 91.9 |
| MMLU-Redux (1,026) | 89.2 | 91.5 |
Same-box speed head-to-heads against 4-bit 9B/27B models in llama.cpp and vLLM are built and staged but not yet run, so no "N× faster than 4-bit" claim is made here.